Tested here
Engagement groupings → calibration, metacognition, offloading, decision atrophy, dependency
Claim boundary: Cross-sectional associations in a pooled observed-composite path model.
Need a different explanation?
Ask the AIEM tutor, or clear this short walkthrough and begin again.
AI Engagement Model · interactive theory walkthrough
Step 12 of 13
The research supports several parts of the model and leaves others open. Start with the findings; open the technical detail when you need it.
About 20–30 minutes · 13 named steps · research detail is optional
The clearest finding is that the workflow matters. AI assistance often improves the work produced in the moment. It does not automatically improve later independent performance, judgment, or motivation. Guardrails that keep the learner evaluating can preserve more of the benefit.
The findings below come from different samples and methods. Their limits stay beside them so a result is not asked to prove more than it measured.
Research on intellectual humility, metacognition, trust calibration, productive failure, reflective practice, cognitive offloading, and learning gives individual AIEM constructs and links a legitimate foundation. It does not collectively validate AIEM as one causal chain.
The fitted model above tests engagement groupings, calibration, metacognition, and three self-reported outcomes. It does not jointly test all five dispositions, all six principles, the eight observed modes, delayed learning, voice, flourishing, or Becoming. Those gaps should remain visible until direct evidence closes them.
How much someone uses AI, how long they have used it, and how many tools they use are the obvious things to measure. The eight modes explain variance beyond all of them: an additional R² of .23 in the sample, .20 under repeated cross-validation.
What this does not show
This says the modes are not redundant with usage. It does not say the modes cause the outcomes they predict.
Working-adult sample, N = 359 (319 with complete data for the full model). Preprint §3.
Seven of the eight modes correlate positively with perceived productivity (r = .20 to .50) and positively with perceived dependency (r = .08 to .48). The same behaviors that make people feel more effective make them feel more reliant.
One mode breaks the pattern. Verification, checking claims and calculations and sources, sits at r = .04 with productivity and r = -.22 with dependency, and is statistically distinguishable from every other mode on both.
What this does not show
These are correlations measured at one point in time. They do not establish that productivity is being traded against dependency over time, and the proposed explanation for why Verification differs was not supported.
Working-adult sample, pairwise n = 358 to 359. Preprint §3.2.
The framework predicts that agency-tier behaviors should look better than passivity-tier ones. What the data show is narrower.
Oracle, asking for a direct answer and accepting it, has the broadest adverse pattern once other modes and usage are controlled for. That half fits. But Verification is the only agency-tier mode whose favorable associations survive correction for multiple comparisons. The other three agency modes do not behave the way a clean ladder predicts.
What this does not show
This is the finding that most constrains what the framework can claim. Passivity, Partnership and Agency are useful teaching groupings; on this evidence they are not a validated hierarchy, and presenting them as one would overstate the result.
Working-adult sample. Benjamini-Hochberg correction across 64 mode-outcome coefficients. Preprint §3.1.
The students reported how they engage with AI, and their real conversations were then coded turn by turn. The correspondence between the two is close to zero. Not one correlation survives correction for multiple comparisons, and the result is stable across three generations of the coding protocol.
What this does not show
This is a measurement finding, not a claim that people are being dishonest. Self-report and behavioral coding are answering different questions, and a gap between them is exactly why both are needed.
Student sample, N = 203, of whom 171 had classifiable paired profiles. Preprint §4.1.
If people could accurately report their own engagement, a survey would be enough and none of the behavioral coding would be necessary.
They cannot, so it is. It also means your intuition about how you use AI is not evidence about how you use AI, which is an uncomfortable thing to learn and a useful one.
Quick check
The tier ordering was tested. What actually held up?
The charts and study summaries below show the evidence behind the practical takeaway. They are here for readers who want the methods and denominators; you do not need to memorize them to use the model.
Public predictions ask whether AI will make people less capable. The current data do not support one universal answer.
In controlled writing tasks, AI assistance improved speed and output quality. In a workplace rollout, access raised customer-support productivity on average, with the largest gains among less experienced workers. Those are real advantages.
Other results show possible costs. Unguarded AI help can raise practice performance while reducing later unaided performance, and confidence in AI is associated with lower self-reported critical-thinking effort. In the same mathematics experiment, a guarded tutor preserved most of the immediate benefit without the later loss.
The contrast is the problem AIEM tries to explain. The important variable is not “AI or no AI.” It is which cognitive work the person keeps, which work the system performs, and what outcome is measured, when.
The percentages are a teaching shorthand. They are not observed population shares, not fixed kinds of people, and they should never be used to classify anyone. They are also not arbitrary, and this is where they come from: three studies, three different downstream outcomes, each reporting how much of the AI-assisted group fell below the comparison group’s average.
| Study | Later outcome | Below | Implied d |
|---|---|---|---|
| Bastani et al. (2025) | later unaided exam | 65% | -0.39 |
| Wu et al. (2025) | intrinsic motivation, solo task | 70% | -0.52 |
| Barcaui (2025) | retention at 45 days | 75% | -0.67 |
| Pooled | unweighted mean of the implied d | 70% | -0.53 |
An overlap is not a prevalence
These studies say where results landed, not what kind of user anyone is. That about 70% of an AI-assisted group scored below the comparison average is a statement about two outcome distributions. It is not a finding that 70% of people use AI passively, and the two get confused constantly.
What each band stands for
So the shape is not arbitrary, and it is also not a headcount. About 70% of AI-assisted participants ended up below the comparison group's average on a later, unaided measure. That is a statement about where two distributions of results sit relative to each other. It is not a finding that 70% of people use AI passively, and the difference between those two sentences is the one most often lost.
Within the rest, whether you call the top group 10% depends on what “clearly better” means. At the comparison group's 75th percentile it is about 12%; at one standard deviation above the mean, the conventional bar and the one a reliable-change calculation lands closest to, it is about 6%. The figure says ~10% because the count is not the point. The band stands for people who used AI to make the work better and themselves better with it, and research does not yet tell us how large that group is or where its upper edge lies.
Quick check
Across these studies, what best describes what AI assistance does?
Students practicing with a plain GPT assistant scored far above the control group on the practice problems, around 78 out of 100 exceeding the control average. On the later exam, taken without assistance, about 65 out of 100 fell below it. A tutored version with guardrails essentially removed the loss, which is the part worth noticing: the tool was not the variable, the way it was used was.
What this does not show
Randomised experiment in one setting with roughly a thousand students. The percentages are an overlap translation of the reported effect sizes, not counts of individual students.
Bastani et al. (2025), PNAS. Effect sizes converted to overlap via Cohen's U3 in the research program's effect-distribution table.
Learners who had worked with AI recalled less than the comparison group after 45 days, 57.5% correct against 68.5%. Around three in four sat below the comparison group's average.
What this does not show
One study, 120 participants. A delayed-retention measure, not a measure of understanding in general.
Barcaui (2025), Social Sciences & Humanities Open.
Collaborating with AI improved immediate task performance. When the same people later worked alone, their intrinsic motivation was lower than that of people who had always worked alone, and the motivation effect was about twice the size of the performance gain in standardized units. Roughly 70% fell below the comparison group's median.
What this does not show
Experimental, and about motivation on a subsequent solo task rather than about ability. Association with later outcomes is not established here.
Wu et al. (2025), Scientific Reports.
Notice what those three studies have in common. None of them says AI made people worse at everything. Each shows a gain and a cost sitting side by side, separated by time and by whether the assistance was still there.
That is why "should we use AI?" is the wrong question, and why "which model?" is barely a question at all. The variable that moved in every one of these studies was what the person did during the hour.
The research scan behind these pages holds 23,402 deduplicated records, from which 81 core or adjacent reports are in the evidence table and 61 are peer reviewed.
It is not a final PRISMA review, and it is not presented as one. Several sources were bounded by retrieval caps, one was unavailable, and a second human reviewer has still to verify the screening decisions. The scan is updated as new work appears, so the numbers on this page are a position at a date rather than a settled result.
Two different things sit behind these pages and they are updated on different clocks.
The findings above come from the research program's own two samples, and they change when a study closes. The wider literature scan around them holds 23,402 deduplicated records, of which 81 core or adjacent reports are in the evidence table and 61 are peer reviewed, as counted in September 2026. That scan is not a completed PRISMA review: some sources were bounded by retrieval caps, one was unavailable, and a second human reviewer has still to verify the screening decisions.
So treat every number on this page as carrying a date. New work enters the evidence table first and only changes what these pages claim after it has been read against the existing set. If a finding here is later narrowed or withdrawn, that will show up as a change to this step rather than as a quiet edit elsewhere.
The typology paper, its methods, and its supplementary material are posted as a preprint. It has not been peer reviewed.
Keith, Wood, & Posey (2026). PsyArXiv. Preprint. Not peer reviewed.
Also at SSRN.
Fitted model, not the whole theory
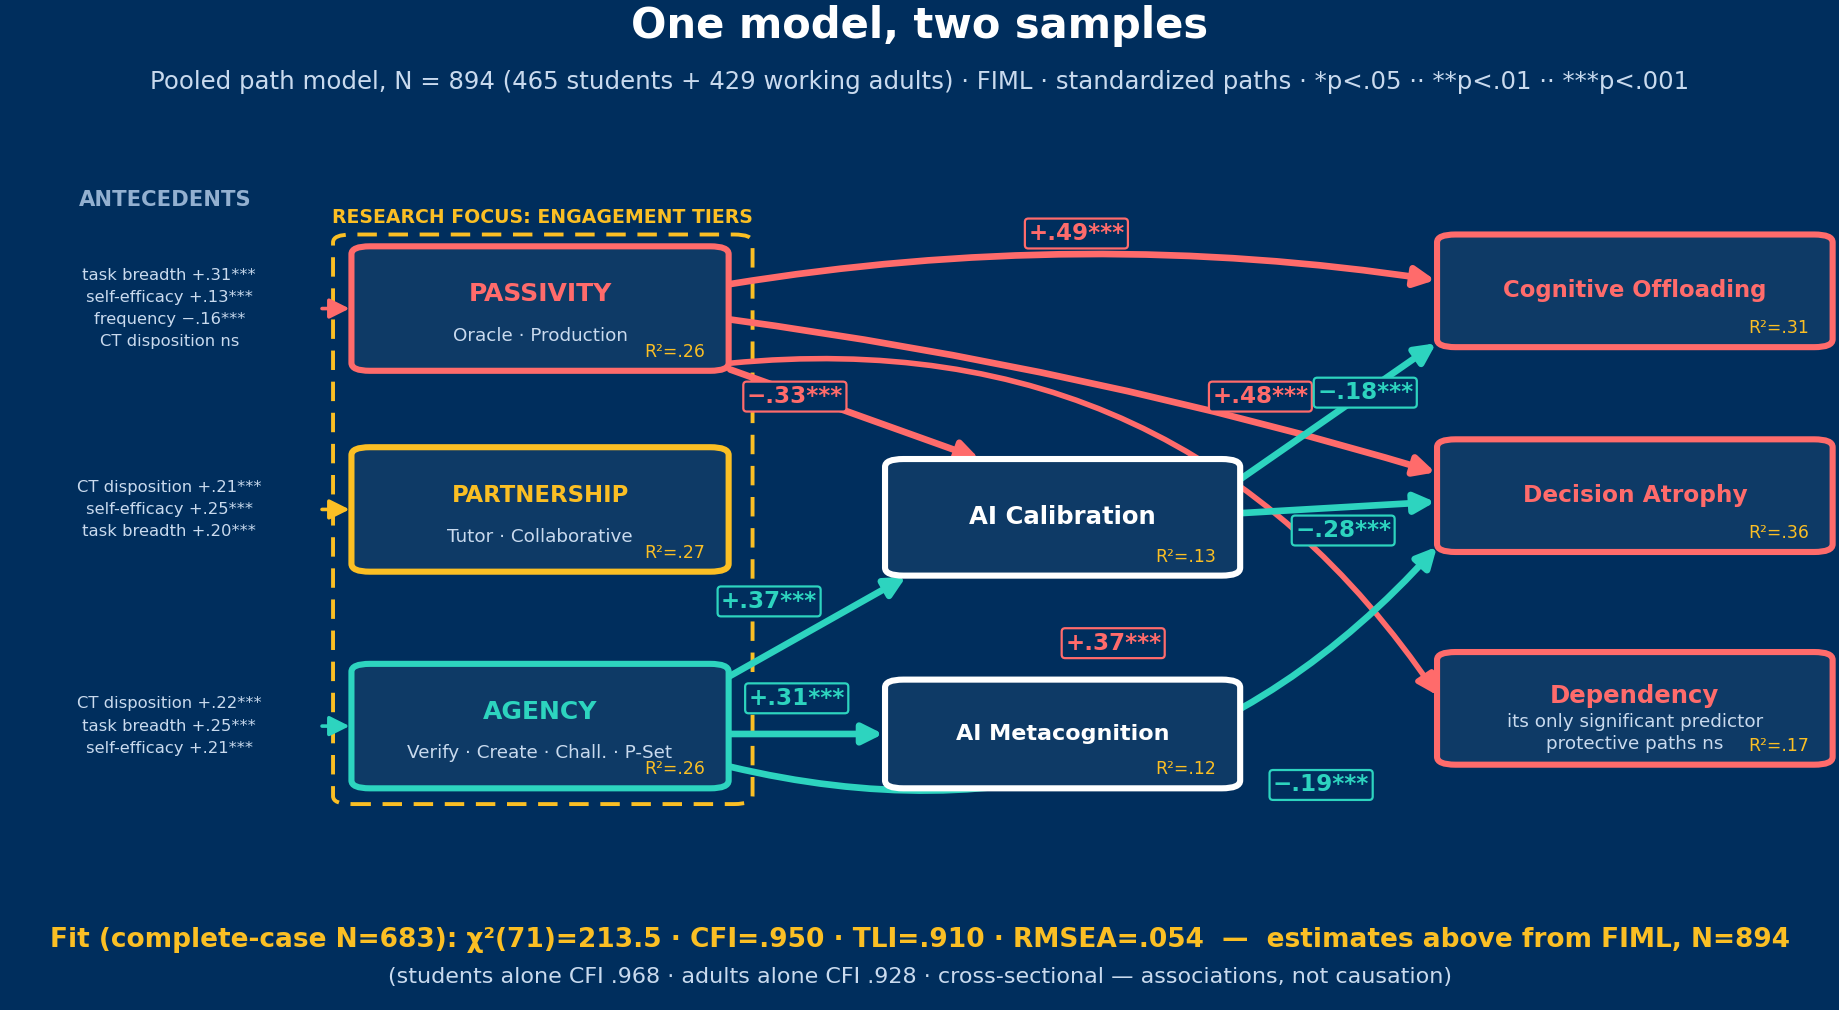 Open the full-resolution fitted model
Engagement groupings → calibration, metacognition, offloading, decision atrophy, dependency
Claim boundary: Cross-sectional associations in a pooled observed-composite path model.
Dispositions and task conditions → engagement groupings
Claim boundary: Some antecedents were measured; the five canonical dispositions were not jointly tested.
Disposition-like tendencies, trust calibration, metacognition, practice, and learning
Claim boundary: Prior studies support individual links or constructs, not the complete AIEM chain.
Full Dispositions → Principles → Behaviors → Outcomes sequence and Becoming loop
Claim boundary: Requires temporal, behavioral, experimental, and longitudinal tests.
| Evidence status | Relationship | Claim boundary |
|---|---|---|
| Tested here | Engagement groupings → calibration, metacognition, offloading, decision atrophy, dependency | Cross-sectional associations in a pooled observed-composite path model. |
| Partly tested | Dispositions and task conditions → engagement groupings | Some antecedents were measured; the five canonical dispositions were not jointly tested. |
| Supported elsewhere | Disposition-like tendencies, trust calibration, metacognition, practice, and learning | Prior studies support individual links or constructs, not the complete AIEM chain. |
| Still proposed | Full Dispositions → Principles → Behaviors → Outcomes sequence and Becoming loop | Requires temporal, behavioral, experimental, and longitudinal tests. |